精读 · 短片 / Reduce / 教程索引
侧翼精读
主线之外的补强:Tiled Matmul 短片把二维切块讲透;B 站 Reduce 讲清归约;官方教程与 Christian Mills 笔记当检索表,不在站上复读全书。
1. YouTube · Tiled Matmul 短片
和合集第 6 讲同构,更短:输出 C 的一块 ↔ 一组 program;K 维滑动取 A/B 片累加。过关:能在纸上画出 BLOCK_M/N/K 三个矩形如何咬合。
for k in range(0, K, BLOCK_K):
    a = load A[tile_m, k:k+BLOCK_K]
    b = load B[k:k+BLOCK_K, tile_n]
    acc += dot(a, b)
store C[tile_m, tile_n] ← acc
2. B 站 · Reduce(BV1kaRzYdEsr)
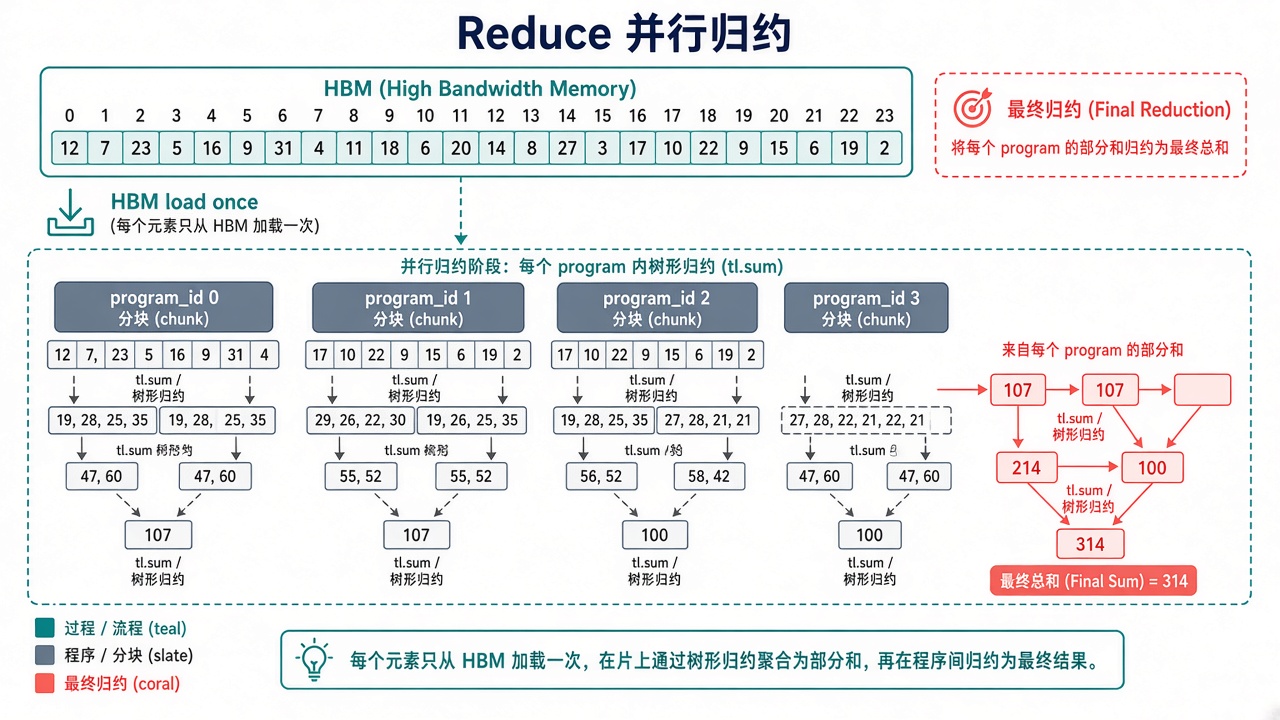
Sum / max 一类:先在 tile 内 tl.sum / 树形归约,必要时跨 program 再归约(或让每个 program 负责一行的全程)。和 Softmax、LayerNorm 共用「行内归约」肌肉。
- 写清 reduction axis,避免把 batch 维误减掉
- 数值:大 sum 注意 dtype;max 注意初值
- 与融合:能在同一 kernel 里 normalize 就别先写出 reduce 结果再读
3. triton-tutorials(官方示例)
当作「标准作业集」:vector add、fused softmax、matmul、FA 教学实现。站上不镜像仓库;用法是——合集精读卡住时,去教程里对同一算子的官方写法。
建议对照顺序:官方 vector add ↔ 合集第 4 讲 ↔ 本地
04b;官方 matmul ↔ 短片 ↔ Lecture 14 设计清单。
4. Christian Mills 笔记
英文长文 + notebook 路线,适合当词典:某个 API(tl.dot、tl.atomic_*、autotune 装饰器)忘了语义就去查。站上只保留定位:本地 gpu_triton/ChristianMills/ 图文索引;不把整本英文搬上来。
怎么插回主线
- 主线卡在 matmul → 先看本节短片伪代码
- 主线卡在 Softmax/LN → 先看 Reduce
- API 细节 → tutorials / Mills
- 编译器问题 → Lecture 29